AI Model Pricing: Same $2 Price, Up to 1.9x the Bill
Claude, Gemini and GPT API prices read from each vendor's page on 14 Nov 2026, rate limits by tier, and our token test: the same paragraph billed 251 to 536 tokens at the same $2 price. Gemini 4 Argon doubles on 1 Dec.
By Duy Lam Le, written with AI11 min read
Why trust this: every result, number and screenshot comes from a real run on our own accounts, not from the AI. How we test
Updated 14 Nov 2026. Every price below was read on the vendor's own pricing page that day, and each section links the page. We re-check the page every Monday and fix a changed price within 48 hours.
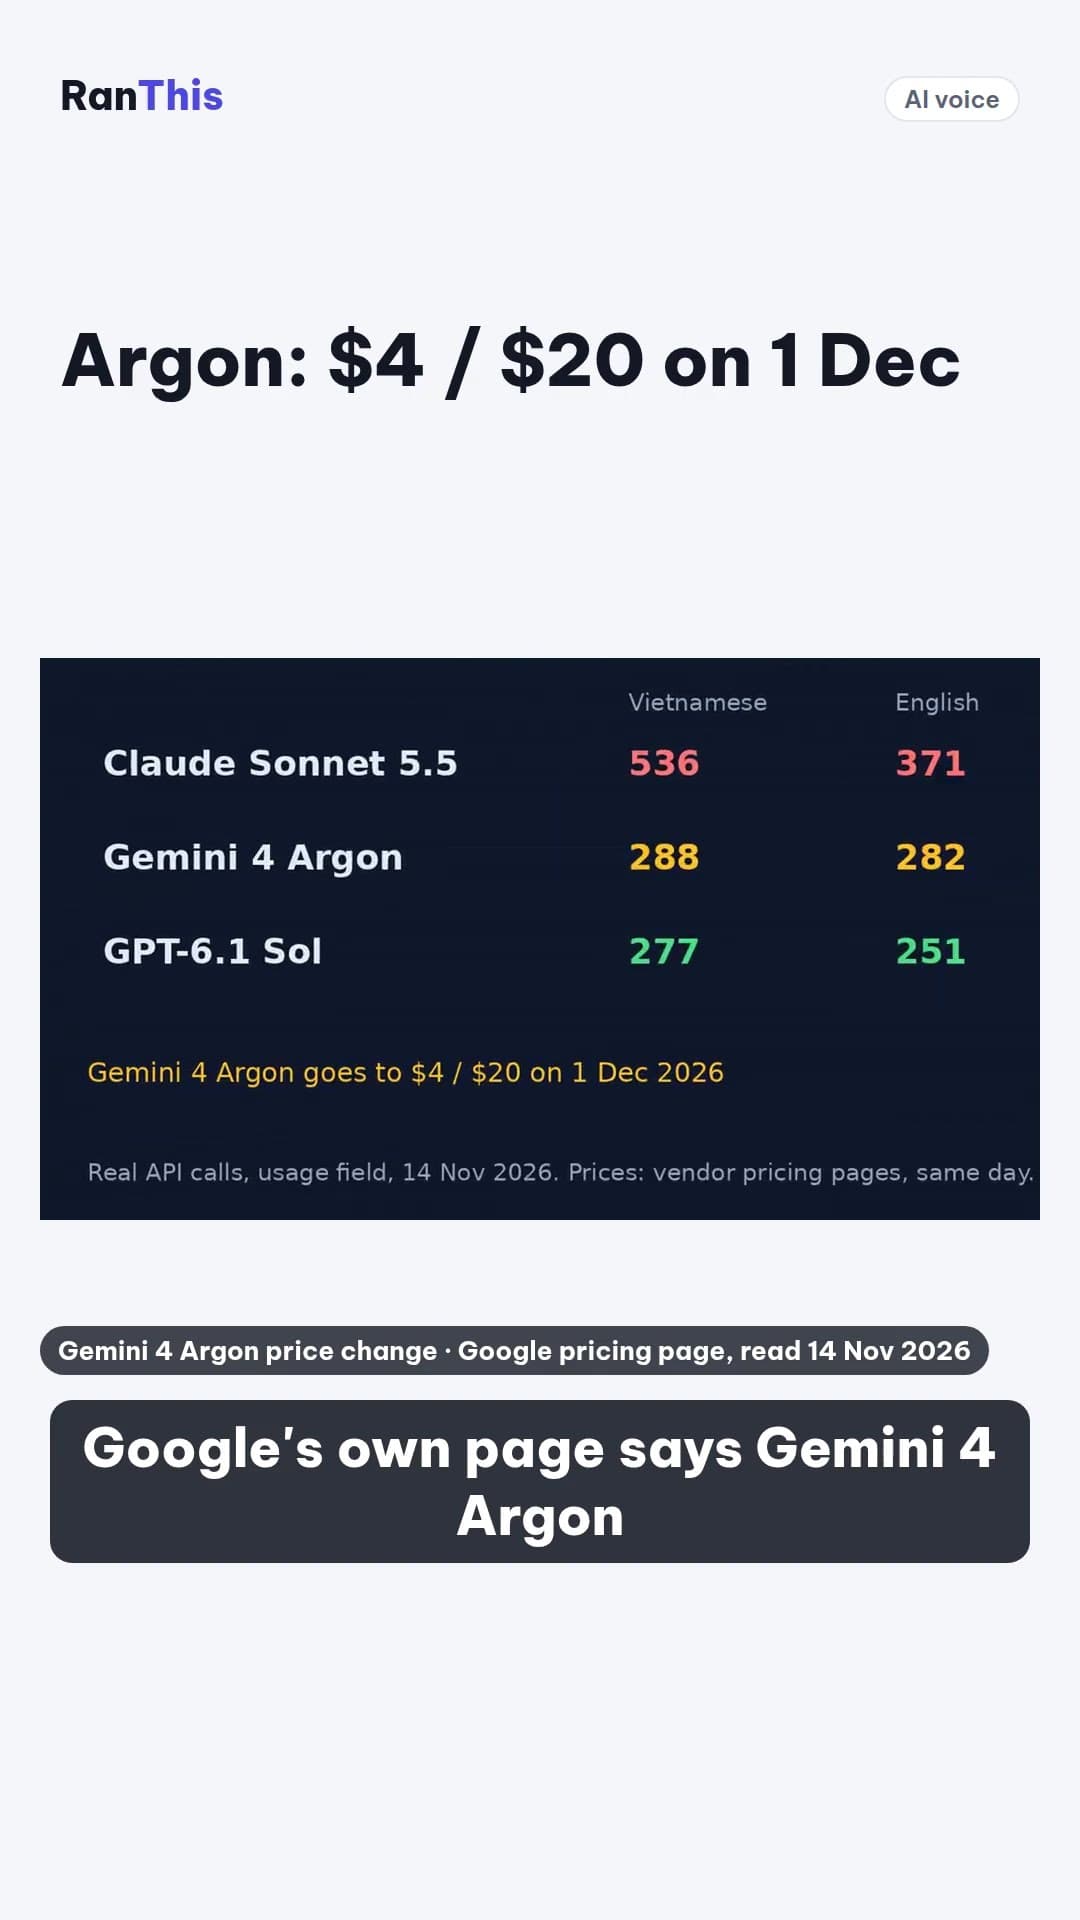
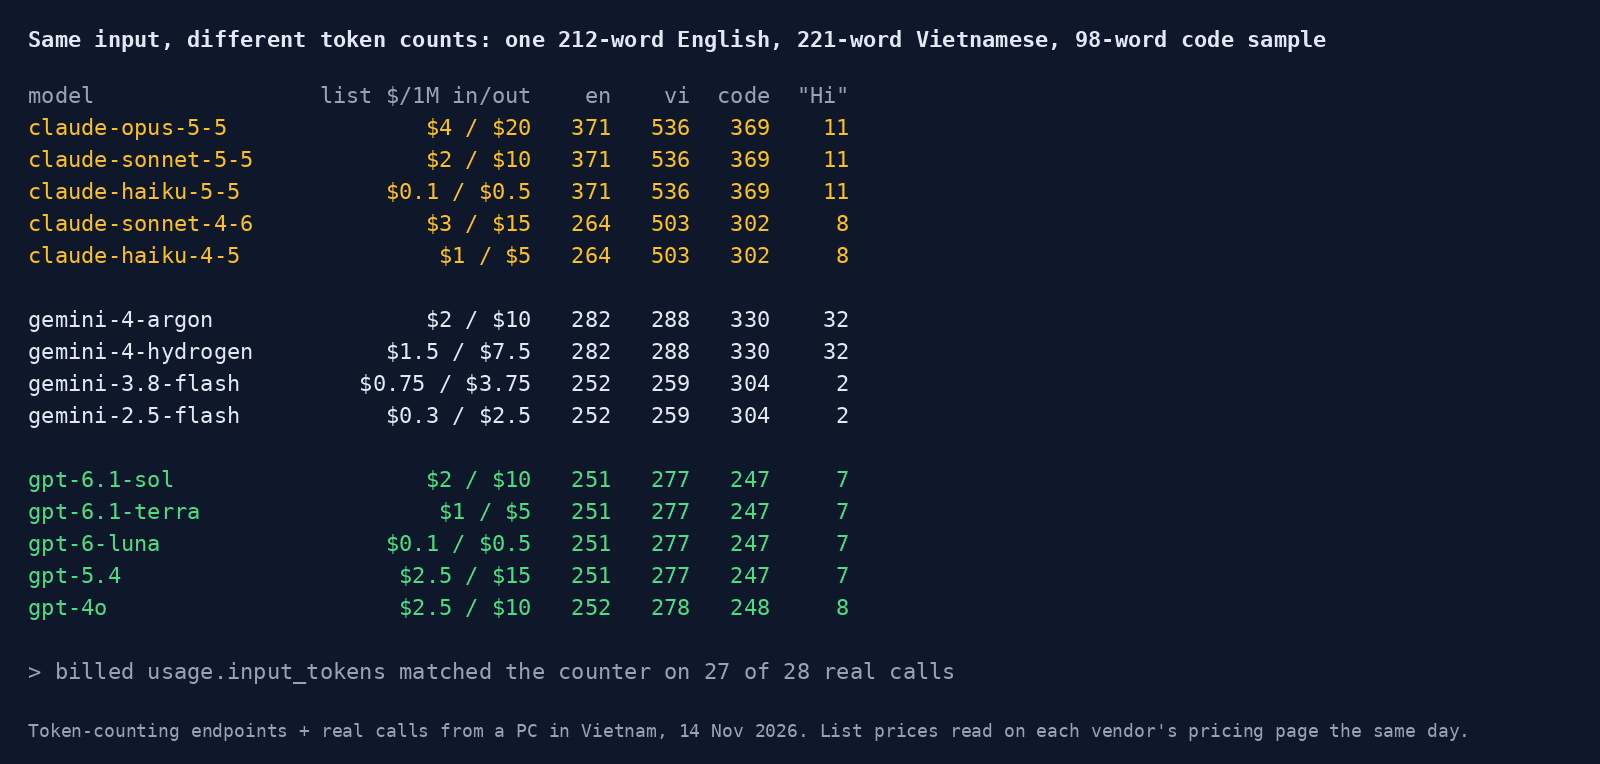
Claude Sonnet 5.5, Gemini 4 Argon and GPT-6.1 Sol all list the same API price today: $2 per million input tokens and $10 per million output tokens. We sent the same paragraph to all three and read the billed token count from each API's usage field. The English paragraph came back as 371, 282 and 251 input tokens. The Vietnamese one came back as 536, 288 and 277. Same sticker, up to 1.9x the bill. On top of that, Google's own pricing page says Gemini 4 Argon doubles to $4 / $20 on 1 December 2026.
This page gives you the list prices with sources, the rate limits per tier, and the token test you need to turn "per million tokens" into a real monthly cost.
At a glance
Key results
- Same list price, different bill. For the same 212-word English paragraph, Claude Sonnet 5.5 billed 371 input tokens, Gemini 4 Argon 282 and GPT-6.1 Sol 251. For the same Vietnamese paragraph: 536, 288 and 277.
- Price changes already scheduled. Gemini 4 Carbon and Argon go from $2 / $10 to $4 / $20 on 1 Dec 2026. Gemini 3.8 Flash goes from $0.75 / $3.75 to $1.50 / $7.50 on 1 Jan 2027.
- Newer Claude, more tokens. The same English paragraph is 371 tokens on Claude 5.5 models and 264 on Claude Sonnet 4.6. Sonnet 5.5 is still cheaper per paragraph because its price is $2 instead of $3.
- Gemini 4 adds about 30 tokens per request. A message that only says "Hi" billed 32 input tokens on Gemini 4 Argon and 2 on Gemini 3.8 Flash.
- The counters tell the truth. On 27 of 28 real calls, the billed
input_tokensmatched the free token-counting endpoint exactly. The 28th (GPT-6 Luna, "Hi") reported 0 tokens in and out. - Rate limits start high. Our own Claude Console organization returned 4,000 requests per minute and 2,000,000 input tokens per minute for Sonnet 5.5, matching the official Start tier.
Hands-on test
Setup
- Date: 14 Nov 2026, from a PC in Vietnam (WSL, Python + httpx).
- Accounts: our own API keys: a Claude Console organization with prepaid credits, a Gemini API project on Tier 1 prepaid billing, and an OpenAI organization.
- Samples: one English paragraph (212 words), one Vietnamese paragraph (221 words) and one short Python file (98 words). They are in our draft repo as
samples.json. - Step 1, count: Anthropic
count_tokens, GeminicountTokensand OpenAIresponses/input_tokensfor 14 models. They generate no text, and Anthropic documents its counter as free. - Step 2, bill: one real request per model and sample for 7 models, capped at 5 output tokens (16 for OpenAI), and we read the billed input tokens from
usage. The whole test cost under $0.03. - Prices: typed by hand from the official pricing pages linked below. We did not take any price from a third-party catalog.
AI model pricing table (November 2026)
Prices per 1 million tokens, standard tier, short prompts, USD. "Cached" is the price to read a cached prompt prefix.
All three vendors give 50% off for batch jobs that can wait. Anthropic's Batch API discounts both input and output by 50%, Google lists its Batch API as a 50% cost reduction, and OpenAI's batch table is half the standard table.
Claude API pricing
Anthropic lists every model on one pricing page. Three details change the bill more than the headline price:
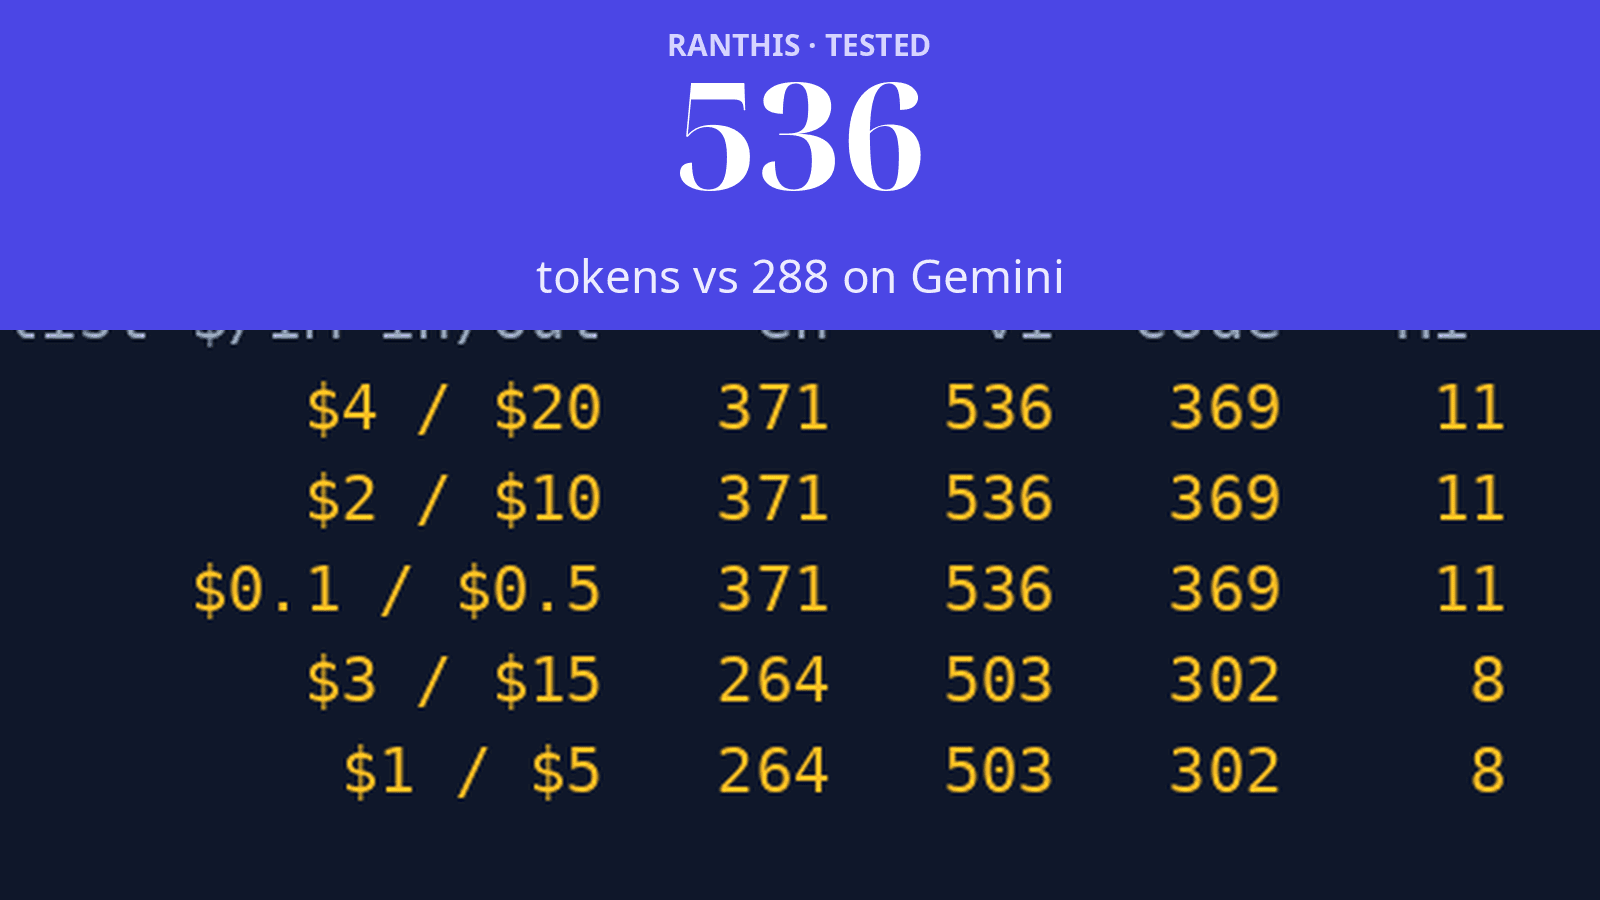
- Tokenizer. Anthropic says Claude 4.7 and later models use a newer tokenizer that produces about 30% more tokens for the same text. In our test the same English paragraph went from 264 tokens on Sonnet 4.6 to 371 on Sonnet 5.5 (+41%), the code file from 302 to 369 (+22%) and the Vietnamese paragraph from 503 to 536 (+7%).
- Cache reads. Opus 5.5 and Sonnet 5.5 charge 0.05x the input price for cache hits. Most other models use 0.1x.
- Haiku 5.5 has two prices. $0.10 / $0.50 for prompts up to 100,000 tokens and $0.50 / $2.50 above that.
Is Sonnet 5.5 more expensive than Sonnet 4.6 then? No, not for the inputs we tried. At $2 per million, 371 tokens cost less than 264 tokens at $3. Per paragraph, Sonnet 5.5 came out 6% cheaper in English and 29% cheaper in Vietnamese.
For what the Claude apps cost, see Claude's plans page: Free, Pro at $20 a month (or $17 a month billed yearly), Max at $100 and Ultra at $200. Pro and Max have usage limits every 5 hours and every week; Ultra drops the 5-hour limit for verified accounts. We measured what eats those limits in Claude Code usage limits.
Gemini API pricing
Google's Gemini API pricing page shows a dated price for several models. Read the dates before you budget:
- Gemini 4 Carbon and Gemini 4 Argon: $2 / $10 "through November 30, 2026", then $4 / $20 "starting December 1, 2026". Neither model is on the free tier.
- Gemini 3.8 Flash and 3.6 Flash: $0.75 / $3.75 through 31 Dec 2026, then $1.50 / $7.50.
- Gemini 4 Hydrogen: $1.50 / $7.50 with no date attached, and it has a free tier.
- Thinking counts as output. The output price "includes thinking tokens". We saw what that does to a bill in Gemini 4 Carbon vs Argon: same price per token, 3 to 4.5 times the cost per task.
Gemini 4 models also count about 30 extra input tokens per request. "Hi" billed 32 tokens on Argon and 2 on Gemini 3.8 Flash. At $2 per million that is $0.00006 per request, so it only matters at millions of short requests.
GPT API pricing
OpenAI's API pricing page splits each GPT-6 model into a short-context and a long-context price. Long context doubles the input price, for example GPT-6.1 Sol is $2 short and $4 long. GPT-5.5 and GPT-5.4 switch to the long-context price at 272K tokens.
GPT-6 models had the smallest token counts in our test for every sample: 251 for the English paragraph, 277 for the Vietnamese one and 247 for the code. GPT-4o counted almost the same (252, 278, 248). If you are moving from GPT-4o to a GPT-6 model, your token counts should barely change.
LLM API pricing comparison: per million tokens is not one unit
A price per million tokens only compares models that cut text into the same tokens. They do not. Here is what 10 million words of input a month costs at list price, using the token counts we measured (input only, output not measured):
How to do this for your own traffic:
- Take 3 real prompts from your app.
- Send each to the token counter of every model you are considering. Anthropic's counter is free; Google and OpenAI also have counting endpoints.
- Divide tokens by words to get tokens per word for each model.
- Multiply your monthly words by that ratio, then by the price.
Do not reuse token counts from an older model. Anthropic's token counting docs say so directly for models before Claude Opus 4.7.
AI model rate limits by tier
Rate limits are per organization (Anthropic, OpenAI) or per project (Google), and they rise with the money you have paid. Each vendor publishes them differently.
Sources: Anthropic rate limits, OpenAI rate limits, Gemini rate limits, all read 14 Nov 2026.
Three things the tables do not tell you:
- New Claude organizations can start lower. Anthropic says new organizations may start in an Evaluation tier below the Start limits until they build usage history.
- Claude does not count cache reads against input tokens per minute. Only uncached input and cache writes count, so caching raises your real throughput.
- Google does not publish per-model RPM for most models. Its docs point you to the rate limit page in AI Studio. If a site lists Gemini RPM for every model, ask where the numbers came from.
You can read your own limits from response headers. Our Claude call to Sonnet 5.5 returned anthropic-ratelimit-requests-limit: 4000 and anthropic-ratelimit-input-tokens-limit: 2000000. Our OpenAI call to GPT-6.1 Sol returned x-ratelimit-limit-requests: 5000 and x-ratelimit-limit-tokens: 1000000. Gemini returned no rate limit headers.
Prices we measured ourselves
This page lists vendor prices. These pages measure what you actually get for them:
- ElevenLabs: seconds of audio per 1,000 credits, by model, in ElevenLabs pricing tested.
- ElevenLabs API key: a free key ran all four text-to-speech models we tried, and Flash v2.5 cost half the credits of the others, in ElevenLabs API key.
- ElevenLabs sound effects: 10 credits per second at fixed length, 50 credits flat on auto length, in ElevenLabs sound effects.
- Higgsfield: credits charged per 5-second clip across seven video models in Higgsfield pricing.
- Claude Code: what uses up Pro and Max limits in Claude Code usage limits.
- Claude skills: five skills run on real tasks in best Claude skills.
- NotebookLM: source and chat limits by plan in NotebookLM limits.
What worked
What worked
- Token counters are reliable. 27 of 28 billed counts matched them exactly, so you can price a workload without spending money.
- Rate limit headers matched the published tier tables, so a single request tells you which tier you are on.
- Google puts scheduled price changes, with dates, inside the price cell itself, so they are hard to miss if you read the page instead of a summary.
Where it fell short
What didn't work
- We measured input tokens only. Output tokens depend on how long each model chooses to answer, so we did not compare them.
- Gemini does not return rate limit headers, and its docs do not list RPM for most models. You have to open AI Studio.
- One OpenAI call (GPT-6 Luna, "Hi") reported 0 input and 0 output tokens. We left it out of the comparison.
- ChatGPT's plans page lists limits as "Limited" or "Unlimited" with no numbers, so we could not put ChatGPT plans in the limits table.
Our verdict
Do not pick a model from the price column alone. At the same $2 / $10 list price, GPT-6.1 Sol was the cheapest of the three for our English and Vietnamese text, and Claude Sonnet 5.5 the most expensive by 1.5 to 1.9 times. If you run Gemini 4 Argon or Carbon, budget for double the price from 1 December. If you write mostly in Vietnamese or another language with accents, count tokens on Claude before you commit, because that is where the gap was largest.
FAQ
Which AI model API is cheapest per million tokens?
Among current models we listed, Claude Haiku 5.5 and GPT-6 Luna both list $0.10 input and $0.50 output. In our test GPT-6 Luna used fewer tokens for the same text, so it was cheaper per paragraph.
Why does the same prompt cost a different amount on two models with the same price?
Each vendor splits text into tokens differently. Our 212-word English paragraph was 251 tokens on GPT-6.1 Sol and 371 on Claude Sonnet 5.5, so the Claude call cost 48% more at the same $2 price.
How often do AI model prices change?
Often enough to date every number. On 14 Nov 2026 Google already listed two future price changes: Gemini 4 Carbon and Argon on 1 Dec 2026, and Gemini 3.8 Flash on 1 Jan 2027.
How this page was made: an AI assistant (Claude) helped write the text and the test scripts. Every price was copied from the linked vendor page on 14 Nov 2026, and every token count comes from our own API calls that day. The RanThis editor checked each number against the source before publishing.
Sources
- Anthropic – Pricing: Sonnet 5.5 $2/$10, Opus 5.5 $4/$20, Haiku 5.5 $0.10/$0.50 per MTok; Batch API 50% off (read 14 Nov 2026)
Vendor page
- Anthropic – Rate limits: Start tier 4,000 RPM, 2,000,000 ITPM for 5.5 models; monthly spend caps $500/$1,000/$200,000 (read 14 Nov 2026)
Vendor document
- Anthropic – Token counting: free to use, count is an estimate, do not reuse counts from pre-Opus 4.7 models (read 14 Nov 2026)
Vendor document
- Claude – Plans: Pro $20/month, Max $100, Ultra $200 with API credits (read 14 Nov 2026)
Vendor page
- Google – Gemini Developer API pricing: Gemini 4 Argon and Carbon $2/$10 through 30 Nov 2026, $4/$20 from 1 Dec 2026 (read 14 Nov 2026)
Vendor document
- Google – Gemini API rate limits: usage tiers, billing tier caps, spend-based limits per 10 minutes (read 14 Nov 2026)
Vendor document
- OpenAI – API pricing: GPT-6.1 Sol $2/$10, GPT-6 Luna $0.10/$0.50 short context; batch half price (read 14 Nov 2026)
Vendor document
- OpenAI – Rate limits: usage tiers Build, Launch, Grow; Build 5,000 RPM and 1,000,000 TPM (read 14 Nov 2026)
Vendor document
- Vietcombank – USD selling rate 25,910 VND on 14 Nov 2026 (VND conversions in the Vietnamese edition)
Other source
- Google – Google AI plans in Vietnam: AI Plus 132,000 VND, AI Pro 489,000 VND, AI Ultra from 2,250,000 VND a month (read 14 Nov 2026)
Vendor page