ElevenLabs vs Gemini TTS: Same 0 Errors, 4.6x Price Gap
We sent one tricky English paragraph through five ElevenLabs and Gemini voice models over the API, three times each. Eleven v4, v4 Turbo and Gemini 3.8 Flash TTS read back with zero errors; Gemini cost $0.0136 a minute, Eleven v4 $0.0624.
By the RanThis team, written with AI8 min read
Why trust this: every result, number and screenshot comes from a real run on our own accounts, not from the AI. How we test
On clean English text, ElevenLabs and Gemini TTS tied on accuracy: Eleven v4, v4 Turbo and Gemini 3.8 Flash TTS all read a tricky paragraph back with zero word errors. The difference is price and speed. Gemini Flash TTS cost $0.0136 per minute of audio, Eleven v4 $0.0624, about 4.6 times as much; ElevenLabs Flash v2.5 was the fastest, about one second per file.
We sent the same 502-character paragraph through five models over their APIs, three times each, and had a third-party model transcribe every result to count the words that came back wrong.
Measured on 5 Nov 2026 from a Python script on a Windows 11 PC in Vietnam (WSL, Ubuntu 24.04), with an ElevenLabs Free account and a paid Gemini API key. Prices were read from both vendors' pricing pages the same morning.
At a glance
Key results
- Accuracy tied on English. Eleven v4, v4 Turbo and Gemini 3.8 Flash TTS each had 0 of 96 words wrong when read back. Flash v2.5 and Gemini Flash-Lite TTS had 2 each, on product names ("Claude Co", "Hixfield", "16 gig").
- Gemini is the cheap option. At list prices, the paragraph cost $0.0078 on Gemini Flash TTS and $0.0053 on Flash-Lite, against $0.0402 on Eleven v4 and $0.0201 on v4 Turbo or Flash v2.5.
- ElevenLabs Flash is the fast option. Flash v2.5 returned the whole 38-second file in a median 1.0 second. v4 Turbo took 3.9 s, Gemini Flash-Lite 5.4 s, Eleven v4 8.8 s, Gemini Flash TTS 10.0 s.
- v4 Turbo is the ElevenLabs model to start with. Same zero errors as v4 in English, half the price, about twice as fast.
- Gemini's price doubles on 1 January 2027. Google's page lists the current Flash TTS output price "through December 31, 2026"; after that the gap with v4 Turbo shrinks from 2.3x to about 1.1x per minute.
- Vietnamese, one run each: Eleven v4 had the fewest errors (3 of 105 words); Gemini Flash TTS had 7 and Flash v2.5 had 8. One run per model is a small sample; treat it as a hint, not a ranking.
Hands-on test
Setup
- Accounts: ElevenLabs Free (10,000 credits a month; this test used 3,751). Gemini API key on a paid AI Studio project (Tier 1).
- Client: Python 3.13 with
httpx, no SDK. ElevenLabsPOST /v1/text-to-speech/{voice_id}withmp3_44100_128; GeminigenerateContentwithresponseModalities: ["AUDIO"], saved as 24 kHz WAV. - Models:
eleven_v4,eleven_v4_turbo,eleven_flash_v2_5,gemini-3.8-flash-tts,gemini-3.8-flash-lite-tts. - Voices: one stock voice per vendor, default settings: "George" on ElevenLabs, "Kore" on Gemini for English and "Umbriel" for Vietnamese.
- Text: a paragraph we wrote to be awkward to read aloud: a version number, a date, dollar amounts, "16 GB", "4:30 pm" and three brand names. 502 characters in English; a Vietnamese version of 493 characters.
- Runs: three per model in English, one per model in Vietnamese. Time is the median wall-clock time from request to full file, not streaming.
- Read-back check: the first file of each model went to OpenAI's
gpt-4o-transcribe, a third party to both vendors. We counted wrong words against the original after normalising how numbers are written ("twenty dollars" and "$20" count as the same), using the same rules for every model.
The script, its JSON output and the scoring rules are kept with the article source. The table below is drawn from that output.
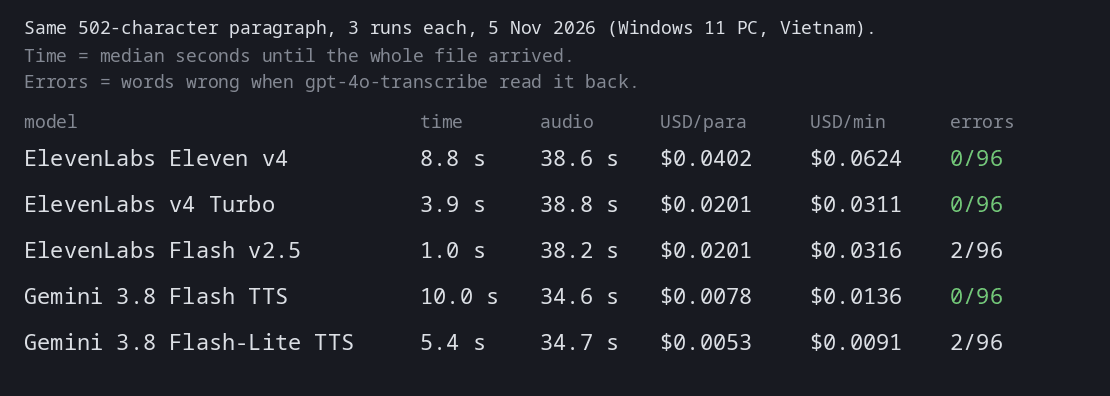
Cost per minute at list prices
| Model | Price basis | Paragraph cost | Audio | Per minute of audio |
|---|---|---|---|---|
| Eleven v4 | $0.08 per 1K characters | $0.0402 | 38.6 s | $0.0624 |
| Eleven v4 Turbo | $0.04 per 1K characters | $0.0201 | 38.8 s | $0.0311 |
| Eleven Flash v2.5 | $0.04 per 1K characters | $0.0201 | 38.2 s | $0.0316 |
| Gemini 3.8 Flash TTS | $0.50 per 1M input tokens, $9.00 per 1M audio tokens | $0.0078 | 34.6 s | $0.0136 |
| Gemini 3.8 Flash-Lite TTS | $0.50 per 1M input tokens, $6.00 per 1M audio tokens | $0.0053 | 34.7 s | $0.0091 |
The two vendors bill on different things, which is why a per-minute figure is the fair comparison. ElevenLabs charges per character of text you send, so a slow, expressive voice gives you more audio for the same bill. Gemini charges mostly for the audio it returns: Google's pricing page says audio tokens correspond to 25 tokens per second, and our token counts matched that (862 tokens for 34.6 seconds). The text going in is a rounding error, 136 tokens for our paragraph.
Our ElevenLabs Free account never saw a dollar charge: it paid in credits. v4 cost 1 credit per character (502), v4 Turbo and Flash half that (251). That matches our earlier ElevenLabs pricing test, where 10,000 Free credits came to about 10 minutes on v4 and 20 on Flash. The dollar figures above are the API pay-as-you-go rates from ElevenLabs' API pricing page, which says API usage "is billed in US dollars, not credits".
Gemini's price is an introductory one. For Flash TTS, Google lists $9.00 per million audio tokens through 31 December 2026 and $18.00 from 1 January 2027; Flash-Lite goes from $6.00 to $12.00. At the 2027 prices, Gemini Flash TTS works out to about $0.027 a minute, still below v4 Turbo's $0.031 but close.
Speed: time until the file is ready
| Model | Run 1 | Run 2 | Run 3 | Median |
|---|---|---|---|---|
| Eleven Flash v2.5 | 1.05 s | 0.92 s | 0.99 s | 0.99 s |
| Eleven v4 Turbo | 4.27 s | 3.89 s | 3.83 s | 3.89 s |
| Gemini 3.8 Flash-Lite TTS | 6.66 s | 5.38 s | 5.28 s | 5.38 s |
| Eleven v4 | 10.07 s | 8.56 s | 8.76 s | 8.76 s |
| Gemini 3.8 Flash TTS | 10.34 s | 10.02 s | 9.81 s | 10.02 s |
This is the time to receive a complete file of about 35–39 seconds of speech, from a home connection in Vietnam. For batch work, such as voicing a video overnight, none of these numbers matters. For anything a person waits on, it does: Flash v2.5 was ten times faster than Gemini Flash TTS. We did not test streaming, where the time to the first audio chunk is what counts, so the gap for live use may be smaller or larger than this.
Which words came back wrong
In English, the misses were all names and units. Flash v2.5 came back as "Claude Co" and "Hixfield"; Gemini Flash-Lite came back as "16 gig" and "Higsfield". Eleven v4, v4 Turbo and Gemini Flash TTS had none.
Vietnamese was harder for everyone. Eleven v4 lost "thắng rõ" (heard as "tháng gió") and "Higgsfield". Gemini Flash TTS had seven misses, mostly tones: "ngay" heard as "ngày", "cần" as "cân", "nâng" as "năng". Flash v2.5 had eight, starting with "Claude Code bản 2.1" heard as "Cloudcode bằng 20 xuong".
This check measures what a machine listener understood, not how natural a voice sounds. Some misses may be the transcriber's fault rather than the voice's, which is why every model went through the same transcriber with the same rules. We did not run a human listening panel.
What worked
What worked
- Both APIs worked on the first call with a plain HTTP client; no SDK, no setup beyond a key.
- The ElevenLabs Free plan was enough to run the whole test, including the newest v4 models.
- Gemini returned exact token counts with each response, so the cost of every call could be checked against the price list.
Where it fell short
What didn't work
- Gemini returns raw audio (PCM) inside JSON, so you have to wrap it in a WAV header yourself. ElevenLabs returns a ready MP3.
- Gemini's paid key still has a daily cap on TTS calls at Tier 1: our project hit it at 100 requests a day in October. With ElevenLabs Free the limit we ran into in earlier tests was the monthly credits and a cap we had set on the key.
- Product names tripped the cheaper models of both vendors. If your script is full of brand names, test them before you choose.
Our verdict
For English voice-overs that are generated in advance, such as videos, courses or articles read aloud, use Gemini 3.8 Flash TTS: in our test it read as accurately as Eleven v4 for about a fifth of the price, and it still wins after the 2027 price rise. Choose ElevenLabs when speed matters or when you are working in Vietnamese: Flash v2.5 returned a full file in about a second, and v4 made the fewest mistakes in our Vietnamese run. If you go with ElevenLabs, start with v4 Turbo rather than v4: same accuracy in English for half the price. Don't pick on accuracy alone; on clean English text, three of the five models were tied.
Try it on your own text: ElevenLabs. Partner link: RanThis is an independent affiliate of ElevenLabs and may earn a commission if you sign up or upgrade through it. We have no affiliate relationship with Google.
FAQ
Is Gemini TTS cheaper than ElevenLabs?
Yes, at list prices. In our test Gemini 3.8 Flash TTS cost $0.0136 per minute of English audio and Eleven v4 $0.0624. ElevenLabs' cheaper v4 Turbo and Flash models cost about $0.031 a minute. Gemini's TTS prices double on 1 January 2027.
Which is faster, ElevenLabs or Gemini TTS?
ElevenLabs Flash v2.5 was the fastest by far: about 1 second for a 38-second file. Gemini Flash TTS took about 10 seconds for the same paragraph, about the same as Eleven v4.
Is Eleven v4 Turbo worse than Eleven v4?
Not in our English test: both read the paragraph back with zero word errors. v4 Turbo costs half as much and returned the file in about 3.9 seconds against 8.8. In Vietnamese, v4 Turbo made 6 errors to v4's 3, on one run each.
Can I use ElevenLabs for free?
Yes. The Free plan includes 10,000 credits a month and API access; our whole test used 3,751 of them. In our ElevenLabs API key test we also found that a key can be capped so it stops before using up the month.
Sources
- ElevenLabs – API pricing: v4 $0.08, v4 Turbo and Flash $0.04 per 1K characters (read 5 Nov 2026)
Vendor document
- Google AI for Developers – Gemini API pricing: 3.8 Flash TTS and Flash-Lite TTS, 25 audio tokens per second (read 5 Nov 2026)
Vendor document
- ElevenLabs Docs – Create speech (text-to-speech endpoint)
Vendor document
- Google AI for Developers – Speech generation (text-to-speech) with the Gemini API
Vendor document