Gemini 4 Hydrogen: Cheaper Tokens Than Argon, 3.7x the Bill
Gemini 4 Hydrogen costs less per token than Argon, but not per task. We ran 3 office tasks and 10 hard maths problems through the API at all 4 thinking levels, against Argon, Carbon and 3.8 Flash: full marks and the fastest answers, but it thinks even at low and cost 2 to 3.7 times as much as Argon.
By the RanThis team, written with AI8 min read
Why trust this: every result, number and screenshot comes from a real run on our own accounts, not from the AI. How we test
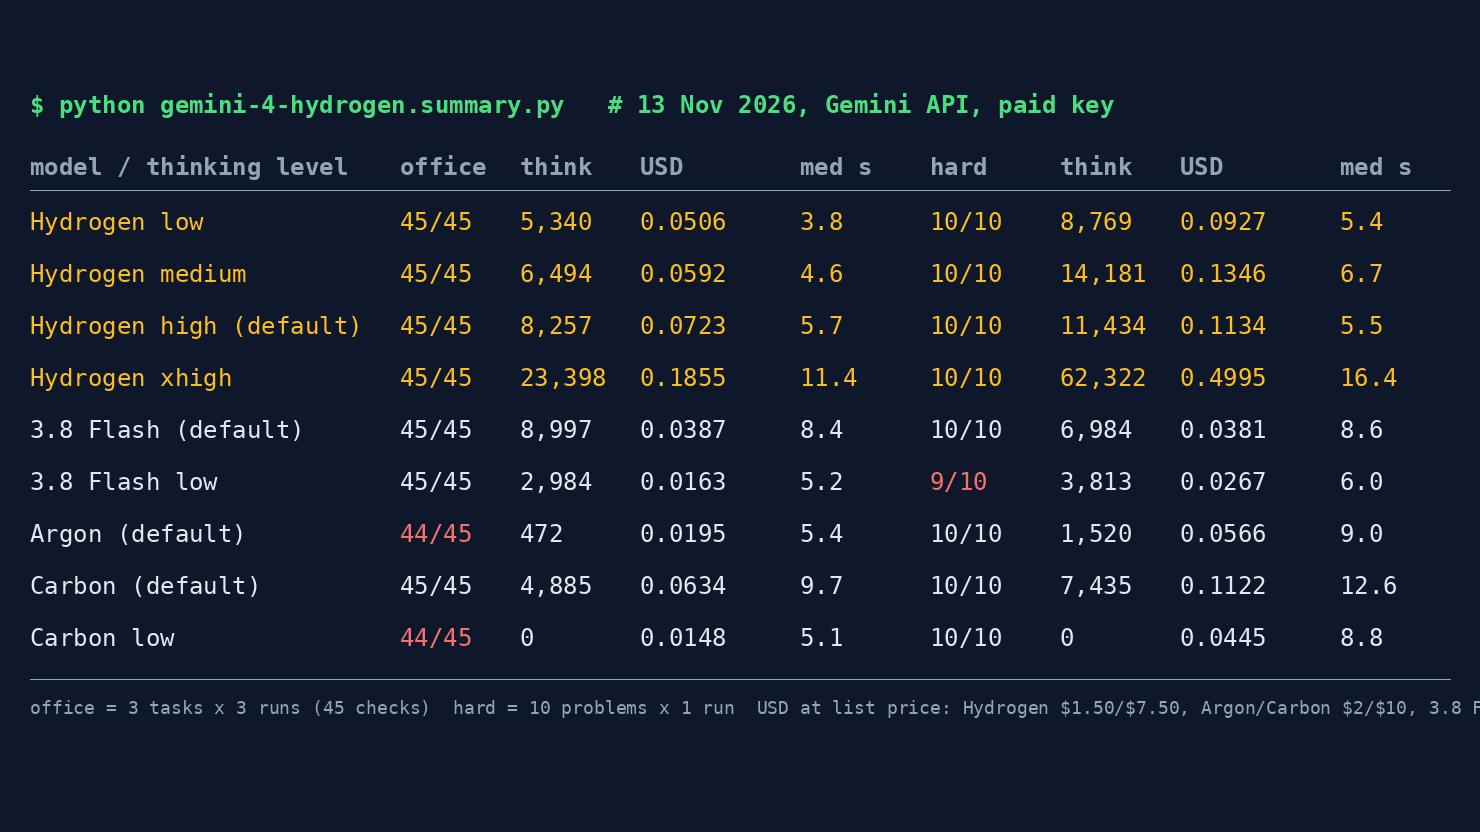
Gemini 4 Hydrogen has the lowest price per token of the Gemini 4 models, but it was not the cheapest per task in our test. It got every answer right and was the fastest model we ran. It also thought on every call, even at low, so at its default level it cost 3.7 times as much as Argon on office tasks and 2 times as much on maths.
We ran the same 3 office tasks and 10 hard maths problems through the API on Hydrogen at all 4 thinking levels, and on Gemini 4 Argon, Gemini 4 Carbon and Gemini 3.8 Flash for comparison.
Measured on 13 November 2026 between 07:09 and 07:15 Vietnam time, about 6 hours after Google released Hydrogen. We called generateContent with our own paid key. Prices and model details come from Google's launch post, the Gemini API pricing page and the What's new in Gemini 4 Hydrogen guide, all read the same morning.
At a glance
Key results
- Every Hydrogen run scored full marks. Office tasks: 45/45 checks at all 4 levels. Hard problems: 10/10 at all 4 levels. Argon and Carbon at
loweach lost one point on an email that ran 1 to 2 words over the limit. - Hydrogen was the fastest. Median time per office call was 5.7 seconds at the default
highlevel and 3.8 seconds atlow, against 8.4 seconds for 3.8 Flash and 5.4 for Argon. - It thinks even at
low. Hydrogen atlowused between 128 and 1,438 thinking tokens per call and never 0. Carbon atlowused 0 on all 19 calls. - Cheaper per token, dearer per task. Hydrogen costs $1.50 per million input tokens and $7.50 per million output tokens. Argon and Carbon cost $2 and $10 until 30 November. Office tasks, 3 runs: Hydrogen (default) $0.0723, Argon $0.0195, 3.8 Flash $0.0387. Hard problems: Hydrogen $0.1134, Argon $0.0566, 3.8 Flash $0.0381.
xhighis expensive and did not help here. It cost $0.4995 on the 10 problems, 4.4 times the default level, with the same 10/10. One integral took 22,508 thinking tokens and 94 seconds.- The free tier is the real news. Google lists Hydrogen as free of charge on the API free tier. Argon and Carbon are paid only.
Hands-on test
Setup
- Models:
gemini-4-hydrogenatlow,medium,high(default) andxhigh;gemini-4-argon(default);gemini-4-carbon(default andlow);gemini-3.8-flash(default andlow). Gemini API paid tier, Standard (not Batch). All four models are listed in our key's model list. - Settings: no
max_output_tokens. The level was set withthinkingConfig.thinkingLevel; "default" means we sent no level. - Office set: the same 3 tasks as our Gemini 4 Carbon vs Argon test: pull 5 invoice fields out of a messy email with a corrected typo, work out tiered sales commission for 5 people with two edge cases, and write an apology email of at most 120 words that ends with a hotline and promises no date. 15 checks per run, graded by code, 3 runs per configuration.
- Hard set: 10 problems with exact answers computed in Python (lattice paths, factorial zeros, divisor sums, expected flips, the integral of ln(sin x), derangements, gambler's ruin, a Diophantine count, a solid's volume, random triangles on a circle). One run per configuration.
- Same-day baseline: Argon and Carbon were run again the same morning, so all numbers below come from one session, not from our 11 November run.
- Cost: input tokens × input price + (visible output + thinking tokens) × output price. The pricing page says output is billed "including thinking tokens". Token counts come from
usageMetadatain each reply. The whole session was 171 calls and cost $1.64.
Benchmarks: full marks, but not cheap
These are our own benchmarks, not a public leaderboard: 3 office tasks run 3 times and 10 hard maths problems run once, on every model and thinking level below.
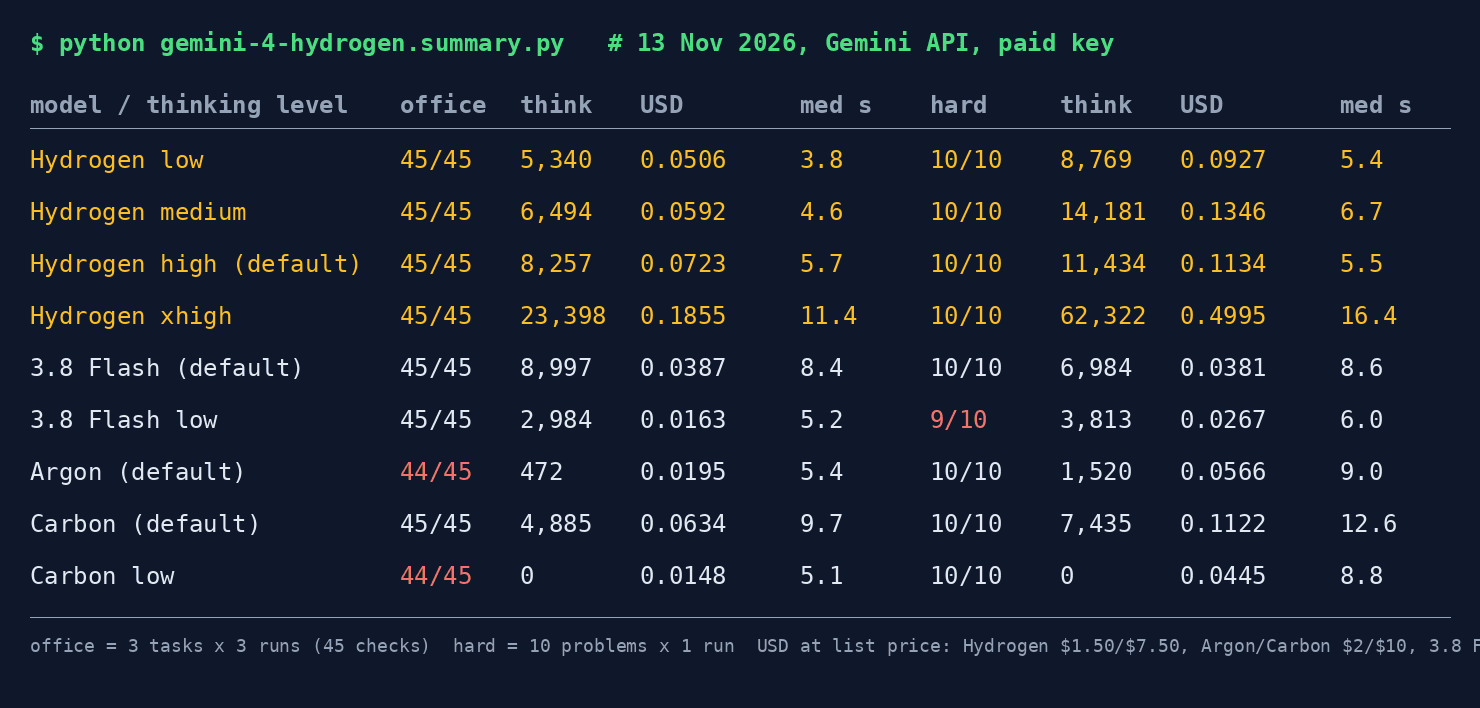
Scaled up, the 3 office tasks run 1,000 times would cost about $24 on Hydrogen at its default level, $17 at low, $13 on 3.8 Flash and $6.50 on Argon at today's prices. Those are straight multiples of our 3 runs, not a forecast for your workload.
On the hard set, medium cost more than the default high ($0.1346 against $0.1134). One problem, gambler's ruin, took 3,996 thinking tokens at medium and 3,314 at high. With one run per problem, read the gap between those two levels as noise.
Where Hydrogen's money goes
The answers themselves were short. On the commission task, which ends with "No explanation", every Hydrogen run wrote the same 72-token table that Argon and Carbon wrote. Before writing it, Hydrogen thought for 813 to 864 tokens at low, about 1,230 to 1,350 at high and up to 6,112 at xhigh. Argon thought for 0 or 236 tokens; Carbon at low for 0.
Google's thinking-level table describes low as "Fewest tokens, lowest latency". That held inside Hydrogen: low was its cheapest and fastest setting. It did not take thinking to zero the way Carbon's low did, so Hydrogen at low still cost 2.6 times as much as Argon on the office set.
The speed claim held up in direction but not in size. Google's post says Hydrogen finishes tasks "2.5 times faster at its high default setting" than 3.8 Flash. On our short tasks it was about 1.5 times faster at high (5.7 against 8.4 seconds median) and 2.2 times faster at low. Google measured agentic work with tool calls, which we did not test.
How to set the thinking level
This is the part of our script that sets the level and works out the cost. Thinking tokens come back in thoughtsTokenCount, separate from candidatesTokenCount, and both are billed as output.
body = {"contents": [{"role": "user", "parts": [{"text": prompt}]}]}
body["generationConfig"] = {"thinkingConfig": {"thinkingLevel": "low"}}  # omit for the default (high)
r = httpx.post("https://generativelanguage.googleapis.com/v1beta/models/gemini-4-hydrogen:generateContent",
               headers={"x-goog-api-key": key}, json=body, timeout=900)
u = r.json()["usageMetadata"]
out_tokens = u.get("candidatesTokenCount", 0) + u.get("thoughtsTokenCount", 0)
usd = (u["promptTokenCount"] * 1.50 + out_tokens * 7.50) / 1e6
What worked
What worked
- Hydrogen handled every trap in the office set at every level: the corrected invoice amount, the person at exactly 200 million dong, the one 500,000 dong short of the bonus, and the one with a returned order.
- Its emails were the shortest of all models, 65 to 108 words against a 120-word limit, so it never lost the point Argon and Carbon lost.
lowwas a clean win within Hydrogen: same score ashigh, 30% cheaper on the office set and 18% cheaper on the maths, and faster.
Where it fell short
What didn't work
lowdoes not mean "no thinking" on Hydrogen. If you are moving short, high-volume calls from Argon or Carbon atlow, expect a bigger bill, not a smaller one.xhighbought nothing on our tasks and cost 2.6 to 4.4 times the default level. Its slowest call took 94 seconds.- Our tasks are short and single-turn. Google aims Hydrogen at coding agents and tool-using workflows, where it claims fewer tokens per task than 3.8 Flash. We did not test that.
- We used a paid key only. We did not test the free tier's rate limits.
Our verdict
Do not pick Gemini 4 Hydrogen to cut costs on short API calls. Its price per token is lower than Argon's, but it thinks on every call. At its default level it cost 2 to 3.7 times as much as Argon on our tasks, and across its low to high levels 1.3 to 3.5 times as much as 3.8 Flash. For cheap, simple, high-volume work, keep Argon, or run Carbon at low while its introductory price lasts. Pick Hydrogen when speed matters more than cost, and run it at low first: on our tasks it was the fastest model at full accuracy. The price picture changes later. Argon and Carbon double to $4 and $20 on 1 December 2026, and 3.8 Flash rises to Hydrogen's $1.50 and $7.50 on 1 January 2027, so Hydrogen's per-task gap will shrink. For learning and prototypes, use Hydrogen on the free tier; our guide to a free Google AI Studio API key shows how to get one.
FAQ
Gemini 4 Hydrogen pricing: how much does the API cost?
According to Google's pricing page, $1.50 per million input tokens and $7.50 per million output tokens on the paid tier, thinking tokens included, flat across the 1 million-token context window. Batch and Flex are $0.75 and $3.75. On the free tier, input and output are listed as free of charge.
Is Gemini 4 Hydrogen cheaper than Gemini 4 Argon?
Per token, yes. Per task, not in our test. At its default high level, Hydrogen cost 3.7 times as much as Argon on 3 office tasks and 2 times as much on 10 hard maths problems, because it used far more thinking tokens.
Is Gemini 4 Hydrogen better than Gemini 3.8 Flash?
On our tasks both scored full marks at their default levels. Hydrogen was about 1.5 times faster and cost 1.9 to 3 times as much. Google recommends Hydrogen as the upgrade from 3.8 Flash and says it makes fewer fabricated claims in agentic work, which we did not measure.
What thinking level should I use with Gemini 4 Hydrogen?
Start with low. In our test it kept full marks, was the fastest setting and cost 18 to 30% less than the default high. Move up only if answers get worse. xhigh cost up to 4.4 times the default with no gain on our tasks.
Can I use Gemini 4 Hydrogen for free?
Yes. Google's What's new guide says Hydrogen "is available on both the free and paid tiers in Google AI Studio and the Gemini API". Google's pricing page also notes that free-tier data is used to improve Google's products and paid-tier data is not.
Claude, the AI assistant, ran the API calls, graded them with code and wrote this page. The figures come from the Gemini API's own usage reports, and each Google claim was checked against the pages linked above.
Sources
- Google Blog – Introducing Gemini 4 Hydrogen: $1.50/$7.50 per 1M tokens, 4 thinking levels, 2.5x faster than 3.8 Flash (read 13 Nov 2026)
Vendor page
- Gemini API – Pricing: Hydrogen $1.50/$7.50 paid tier and free of charge on the free tier; Argon and Carbon $2/$10 to 30 Nov; 3.8 Flash $0.75/$3.75 (read 13 Nov 2026)
Vendor page
- Gemini API – What's new in Gemini 4 Hydrogen: free and paid tiers, thinking levels low/medium/high (default)/xhigh, upgrade from 3.8 Flash (read 13 Nov 2026)
Vendor document
- Gemini API – Available regions: Vietnam listed (read 13 Nov 2026)
Vendor document
- Hacker News – discussion of the Gemini 4 Hydrogen launch, 12 Nov 2026
Community
- Vietcombank – USD selling rate 25,870 VND, 07:03 on 13 Nov 2026 (VND conversions in the Vietnamese edition)
Other source